Image, video and audio references in one prompt
MiniMax H3 takes up to 9 reference images, 3 reference videos and 3 audio clips in one generation, and it reads them together rather than one at a time. MiniMax's own example asks the model to copy the camera move from a video, have the character from an image sing, and match the vocals to an audio clip, all in one sentence. The prompt is where you say what each reference is for: "keep the face and the navy sweater from the portrait, follow the dolly move in the reference video, and have him sing the melody from the audio clip on the harbor at dusk". Without that sentence the model has to guess which input controls what. References and a first or last frame cannot be combined in one generation, so choose one approach per clip, and pick H3 in the model menu for clips built on references. Use your own material, or material you have permission to use, especially for faces and voices.
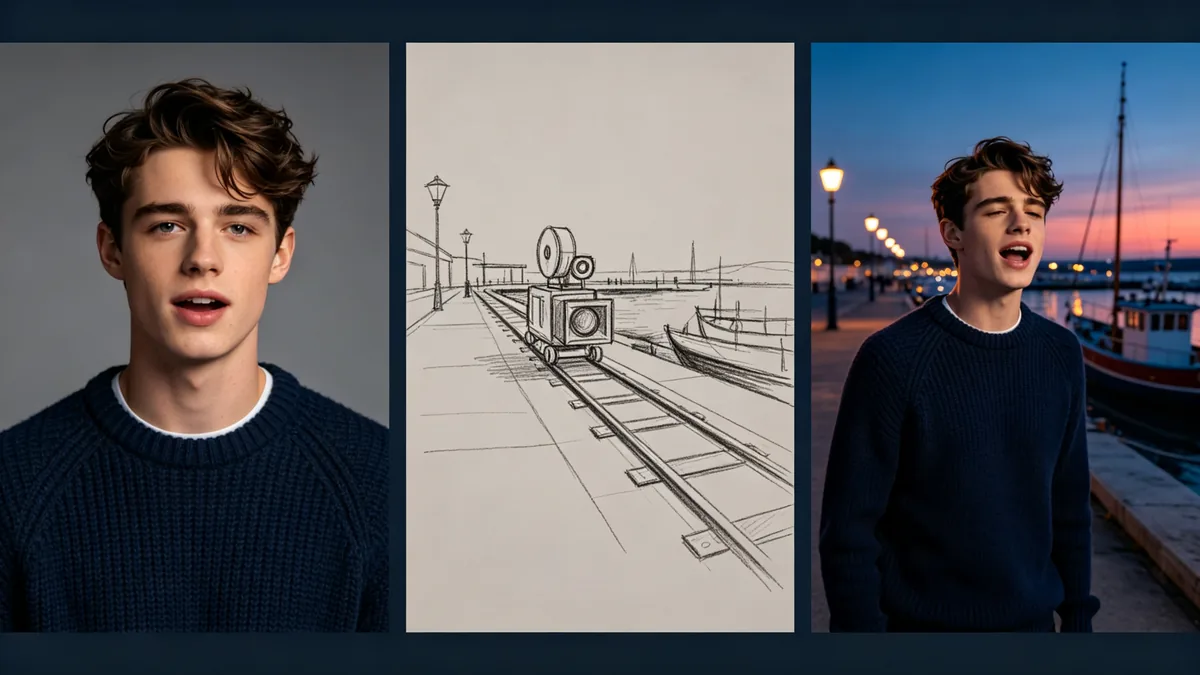
Cinematic 16:9 video keyframe, a triptych of three panels separated by thin dark gutters: left, a plain studio portrait of a young man in a navy knit sweater against a grey backdrop; middle, a pencil storyboard sketch of a camera dollying along a harbor quay; right, the same young man in the same navy sweater singing on the harbor quay at dusk as the camera moves alongside him, moored boats and lamps behind. Consistent face and clothing across the panels, deep blue and coral palette, no text, no logos.